
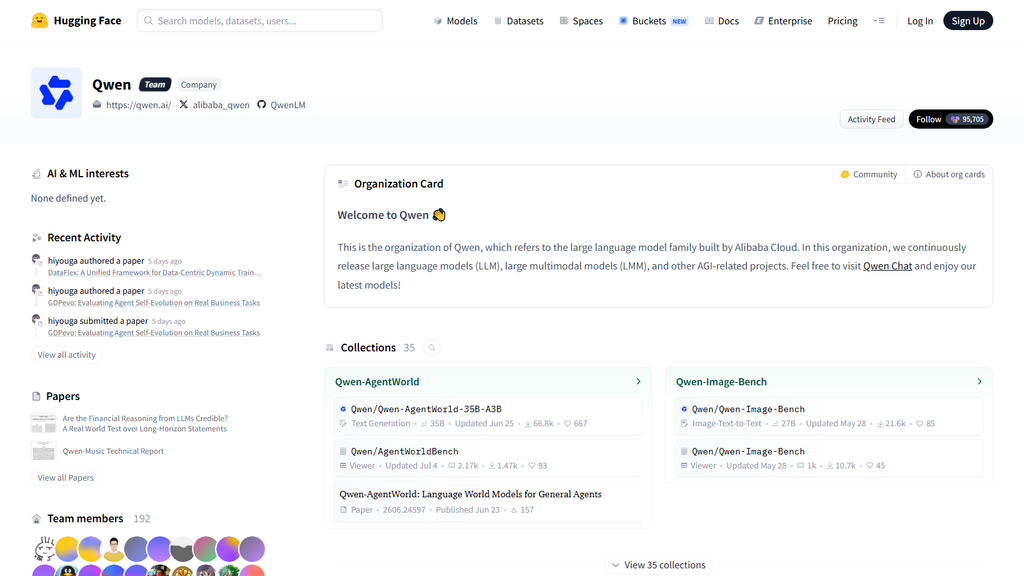
Alibaba has not published Qwen 3.8 27B yet — as of August 9, 2026 there is no official `Qwen/Qwen3.8-27B` repository. Search Hugging Face for it anyway and you will get results, because repositories named for unreleased models appear as soon as the announcement does. At least one of them contains no weights at all and says so in its own model card.
This is a normal and mostly harmless phenomenon that becomes a real problem the week a popular model actually drops, when download traffic spikes and nobody reads carefully. Here is how to check.
What’s actually there right now
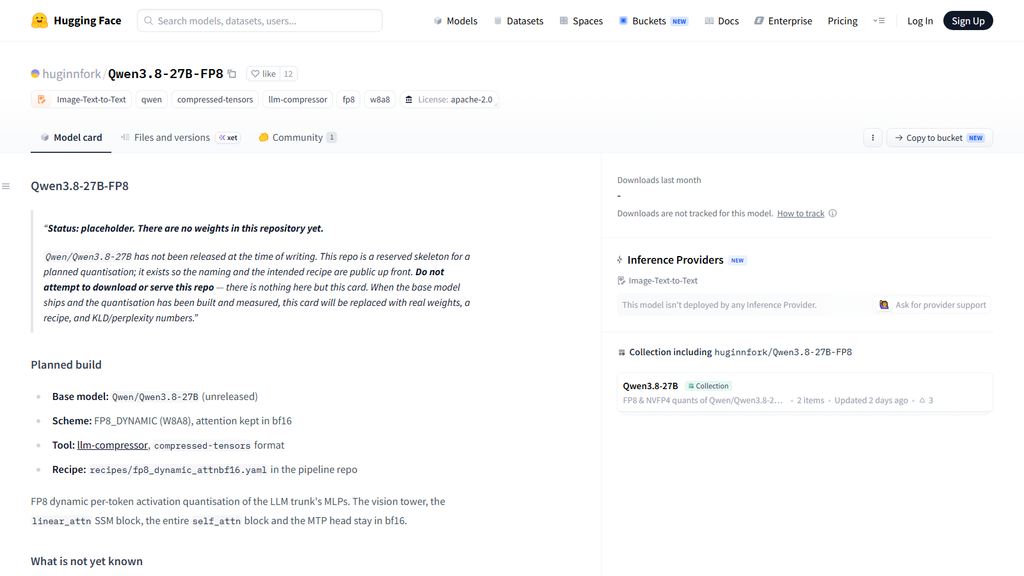
We looked at `huginnfork/Qwen3.8-27B-FP8` on August 9. It is worth walking through because it’s a textbook example of a *legitimate* placeholder — and knowing what a legitimate one looks like is how you spot an illegitimate one.
• Owner: `huginnfork`. A third-party account, not Alibaba.
• Contents: nothing. The card states *”Status: placeholder. There are no weights in this repository yet.”*
• The warning: *”Do not attempt to download or serve this repo — there is nothing here but this card.”*
• Stated intent: a planned FP8 dynamic (W8A8) quantisation via llm-compressor, attention kept in bf16 — of a base model that doesn’t exist yet.
• Licence on the card: Apache-2.0 — but that is *the uploader’s card*, not a statement about the base model’s licence, which Alibaba has not announced.
That last point is the subtle one. A quantiser’s repository inherits whatever licence the base model carries. If the card asserts a licence before the base model has one, the assertion is aspirational, however well-intentioned.
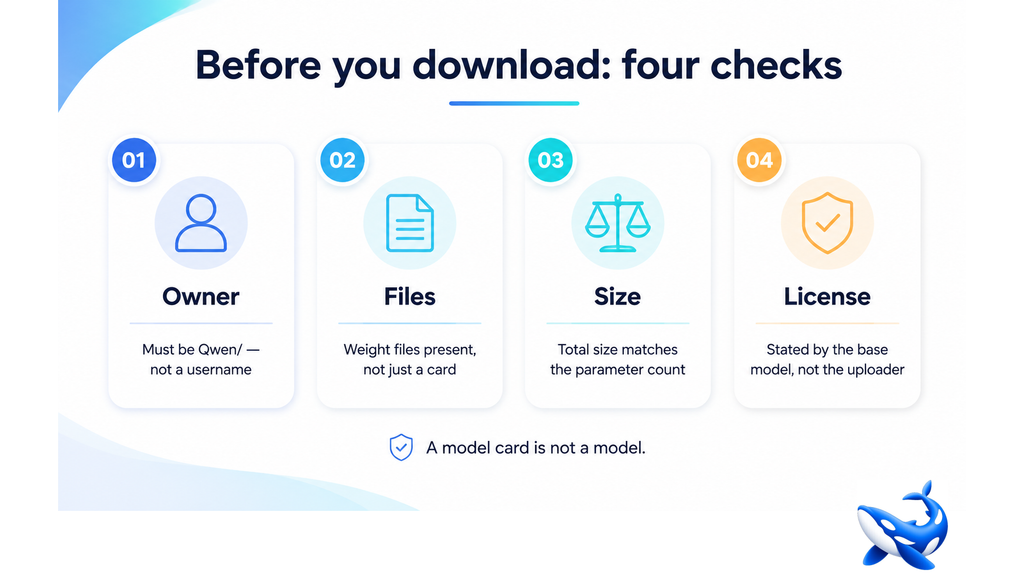
The four checks
1. The owner is the vendor. For this model that means the repository path starts with `Qwen/`. Everything else — `someuser/Qwen3.8-27B-GGUF`, `otheruser/Qwen3.8-27B-AWQ` — may be a perfectly good community quantisation, but it is downstream of a source you should verify first. Mirrors and quants are normal; they are just not the source of truth.
2. Weight files are actually present. Open the Files tab. You want `.safetensors` shards (or `.gguf` for a quantised build) with real byte counts. A repository containing only `README.md` and `config.json` is a placeholder no matter what the card says.
3. The total size is arithmetically sane. This is the check that catches the most nonsense, and it’s simple. A 27-billion-parameter model needs roughly:
• ~54 GB at BF16/FP16 (two bytes per parameter)
• ~27 GB at FP8 (one byte)
• ~14–16 GB at 4-bit
If a repo claims to be full-precision 27B and the files total 3 GB, it is not what it says it is. If it claims 4-bit and totals 60 GB, something is equally wrong. These are arithmetic on the parameter count rather than measurements, but they are close enough to catch fabrications instantly.
4. The licence comes from the base model. Until Alibaba publishes one, *no* repository can honestly tell you the licence of Qwen3.8-27B. Qwen 3.5 and 3.6 both shipped Apache-2.0, which is a strong pattern — but a pattern is not a commitment, and a third party restating it does not make it true.
Why this gets worse on drop day
Right now the risk is low, because the placeholders are honest and the traffic is small. Both change when the weights actually land.
The pattern with any popular open-weight release is that within hours there are dozens of derived repositories — GGUF conversions, AWQ and GPTQ quantisations, fine-tunes, merges, “uncensored” variants. Most are genuine community work and some are excellent. But the volume makes it easy to grab the wrong one, and the differences are not cosmetic: a quantisation changes quality, a fine-tune changes behaviour, a merge changes both, and an abliterated variant has had its safety training deliberately removed.
The specific failure mode to avoid is assuming a repo is the base model because the name matches. Read the card. A conscientious quantiser will say exactly what they did — the placeholder above, for instance, states plainly that it’s “a plain quantisation — no abliteration, no fine-tuning, no merging.” That sentence is the kind of thing you should be looking for.
What to run while you wait
The practical alternative to refreshing the hub is to run something that already exists. Several genuinely open models sit in the same size class and are downloadable today: Gemma 4 12B under Apache-2.0, Ling 3.0 Flash and Motif-3 under MIT. Any of them will tell you whether your hardware, your serving stack and your workload actually suit local inference — which is knowledge you’ll want *before* the model you’re waiting for arrives, not after.
If what you need is Qwen3.8-generation capability rather than local weights specifically, the flagship is already callable. Qwen3.8-Max — 2.4 trillion parameters, roughly 95B active, 1M context, $2 / $6 per million tokens — has been live since announcement day and carries the generation’s only independent score, an Artificial Analysis Intelligence Index of 56 at about $1.14 per task. You can call Qwen 3.8 Max today — no repository to verify, no weights to wait for.
A short checklist to save
Before you `git clone` anything named after this model:
• Path starts with `Qwen/`
• Files tab shows `.safetensors` or `.gguf` with real sizes
• Total size roughly matches ~54 GB (BF16), ~27 GB (FP8) or ~14–16 GB (4-bit)
• The card names the licence *and* Alibaba has actually published one
• If it’s a derivative, the card says what was done — quantisation, fine-tune, merge, abliteration
The takeaway
There are already repositories on Hugging Face named for a model that doesn’t exist yet, and the one we checked is completely empty by its own admission. That’s harmless today and won’t be on drop day, when a hundred derivatives appear within hours. The four checks — owner, files, size arithmetic, licence provenance — take about thirty seconds and will save you from serving something that isn’t what you think it is. Until then, the most productive thing you can do is prove out your serving stack on a model that’s actually downloadable.
Sourcing note: the contents and wording of `huginnfork/Qwen3.8-27B-FP8` were verified on Hugging Face on August 9, 2026 and may change. The absence of an official `Qwen/Qwen3.8-27B` repository was verified the same day. Memory figures are arithmetic on a 27-billion-parameter count, not measurements, and exclude KV cache. Alibaba has published no licence for Qwen3.8-27B; the Apache-2.0 precedent from Qwen 3.5 and 3.6 is a pattern, not a commitment.